Observability that actually helps in an incident
During an incident, most people open Grafana first. Everything green. That’s exactly where the team gets stuck.
- Date
- Topic
- Observability
- Sources
- 2
- Reading time
- 2 min
- Version
- Translation
During an incident, most people open Grafana first. Request rate, p99, CPU, all green. And that’s exactly where the team gets stuck.
Figure as text
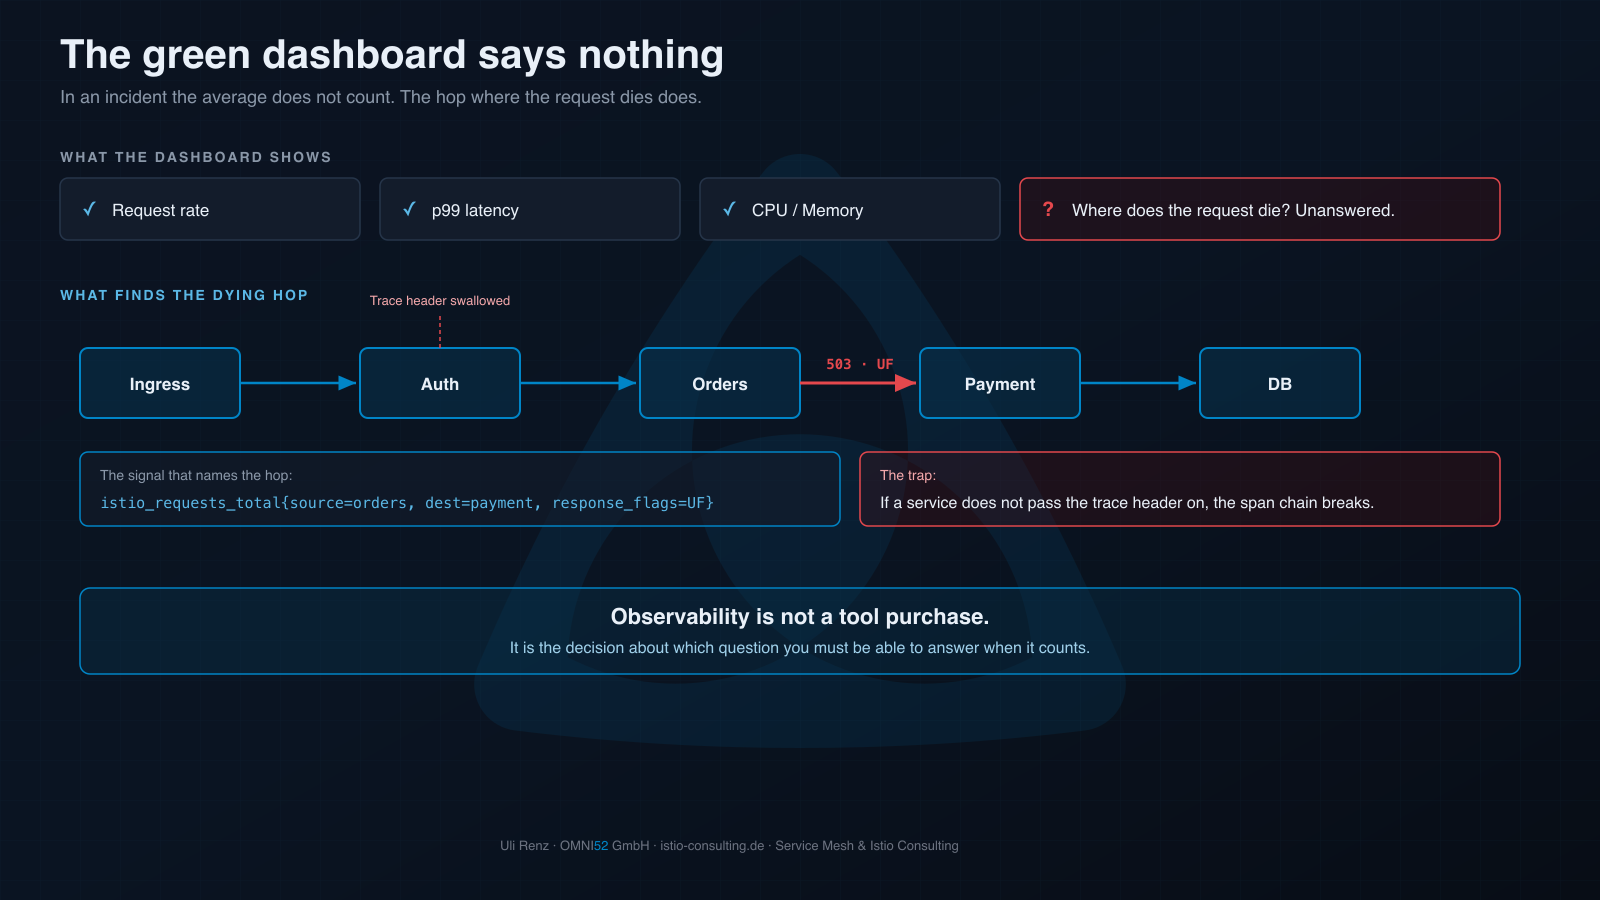
Green aggregate tiles for request rate, p99, and CPU next to the unanswered question "Where does the request die?". Below them, a service chain from ingress via auth, orders, and payment to the database with one red hop (503, flag UF), an istio_requests_total query as the key signal, and a span chain that breaks where a service drops the trace headers; closing line: observability is not a tool purchase.
Because green only means one thing here: on average, everything is fine. It says nothing about where, in a chain of five services, the one request this incident is actually about dies. The aggregate beats the single case, and an incident is always the single case.
The signal that actually helps is less glamorous. istio_requests_total, broken down by source and destination, by response_code and response_flags. One query, and “something is hanging” becomes “service A to service B, 503, flag UF”. The exact flag from the previous report, now visible across the entire mesh instead of in a single pod’s log.
With multiple hops, the trace comes into play. The span chain shows the hop where latency explodes or the call breaks off. Here’s the trap: Istio generates the spans, but propagating the trace headers is up to the services themselves. One service that swallows the header, and the chain breaks. Then you have gapless dashboards with a gap exactly where it hurts.
Kiali turns that into a picture. The graph shows the red edge where the traffic tips over. Three letters become a topology.
The point is not the tooling. Prometheus, Kiali, and tracing already come bundled with most Istio setups. What’s missing is the decision about which question your team must be able to answer when things go wrong, and making trace header propagation mandatory for every service instead of optional.
Which signals we really need in an emergency, and that every service propagates the trace headers, no exceptions: that’s the first thing I nail down in assessments. Not because the dashboard is missing. Because it answers the wrong question.
A green dashboard is not proof that things are working. It’s proof that nobody is measuring the right question.
Which signal actually pointed you to the dying hop in your last incident? And which green dashboard gave you the silent treatment?