The scariest error message usually has the most mundane cause
Most mesh incidents aren’t hard. They just look that way.
- Date
- Topic
- Debugging
- Reading time
- 2 min
- Version
- Translation
Most of the mesh incidents I see aren’t hard. They just look that way.
Figure as text
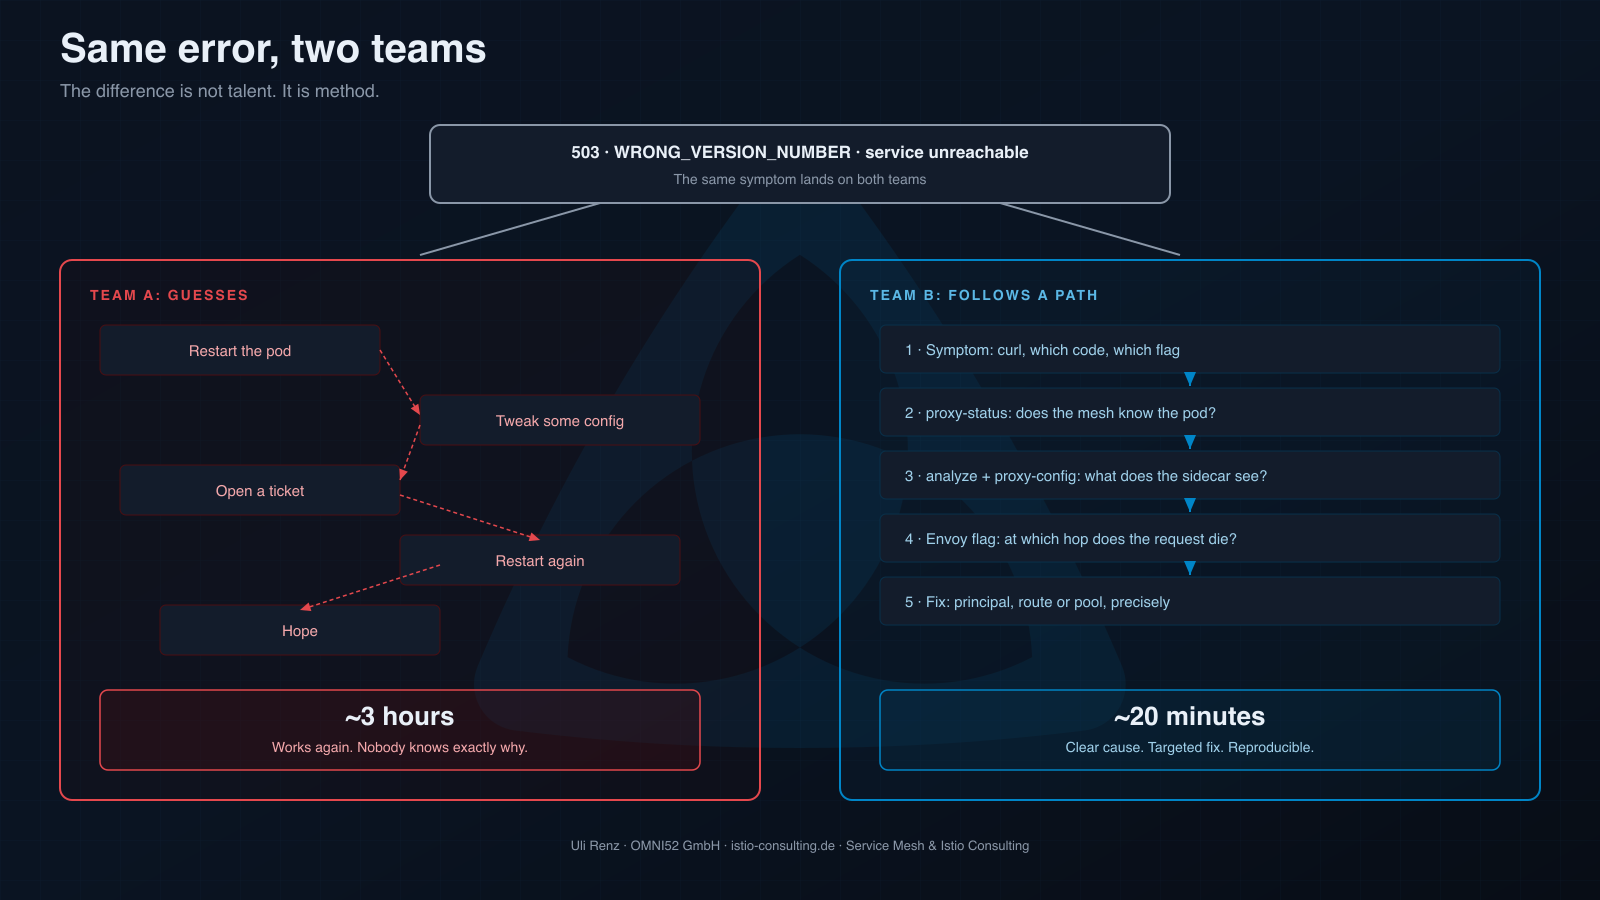
Diagram comparing two teams debugging the same symptom, shown at the top: Team A guesses and follows a chaotic zigzag path that takes about 3 hours, while Team B follows a straight, systematic path of istioctl steps and reaches the cause in about 20 minutes.
Here’s an example almost everyone who runs Istio knows. A service suddenly can’t reach another one. The sidecar log shows this:
“upstream connect error … WRONG_VERSION_NUMBER”
If you’re seeing this for the first time, you think broken certificates, a TLS misconfiguration, something deep in the encryption stack. Teams lose hours on this.
The cause is almost always mundane: the target pod has no sidecar. Someone forgot the namespace label for injection. The caller speaks mTLS, the target answers plain HTTP, and to the proxy the first byte looks like an invalid TLS version. Terrifying message, trivial root.
Same pattern with 503s. The status code alone tells you nothing. But Envoy writes a flag next to it, and that flag is half the diagnosis. UF means the upstream connection failed, often a missing sidecar or an mTLS mismatch. NR means no route, a Gateway or VirtualService pointing at nothing. UO means the circuit breaker tripped. Three letters, three completely different problems.
The real point isn’t the individual error message. It’s the difference between two teams.
One team guesses. It restarts pods, tweaks configs, opens tickets, and hopes. Three hours later everything works again, and nobody knows exactly why.
The other team has a fixed path. Symptom, then proxy-status: does the mesh even know about the pod. Then analyze and proxy-config: what does the sidecar actually see. Then the Envoy flag: at which hop does the request die. Twenty minutes, clear cause, targeted fix.
The difference isn’t talent. It’s method. And method is something your organization can put in place long before the next incident hits.
If your team regularly debugs the mesh blind, you don’t have a staffing problem. You have a missing runbook.
Next week: the diagnostic path as a concrete step-by-step sequence you can hand to your whole team.